RUNHUG
Find the best model.
Deploy it in minutes.
Run it for pennies.
Search Hugging Face, deploy on RunPod serverless vLLM or GCP Spot llama.cpp, then chat via an OpenAI-compatible URL, Claude Code, or OpenCode — including heretic builds trained in-CLI.
 Hugging Face

 Google Cloud
 vLLM
 llama.cpp
 Claude Code
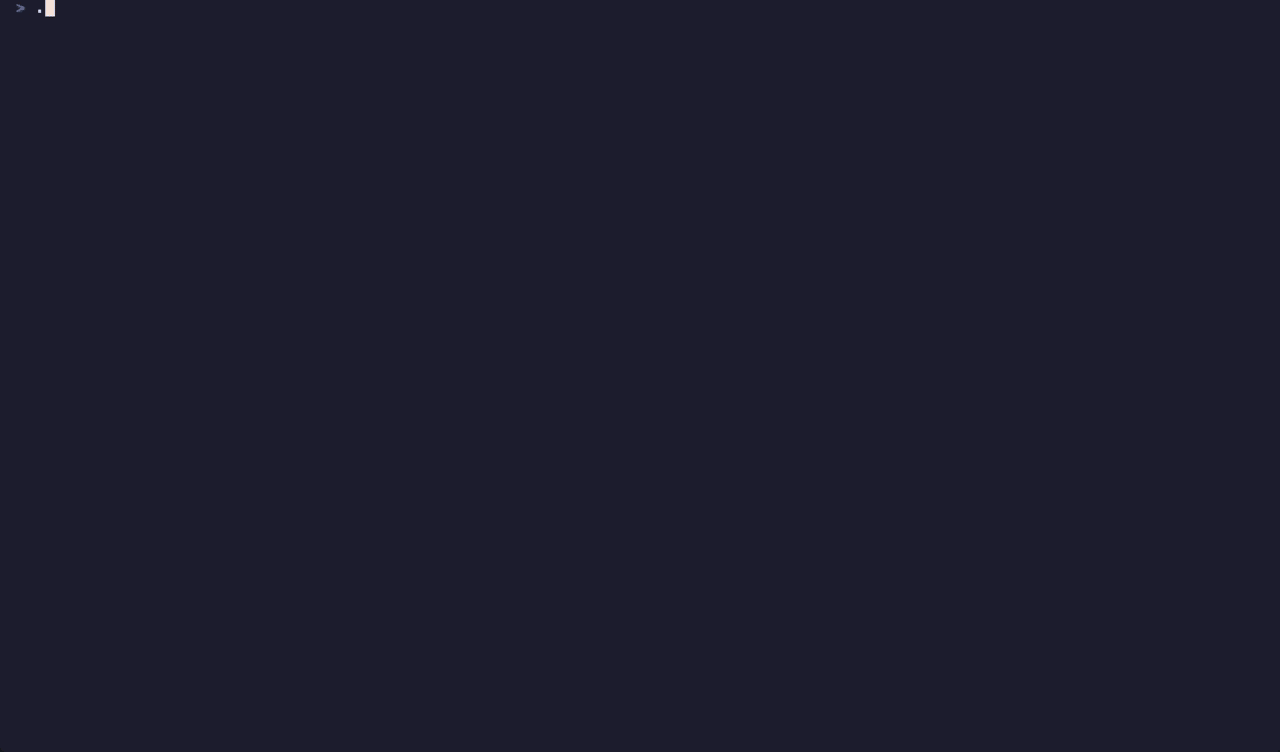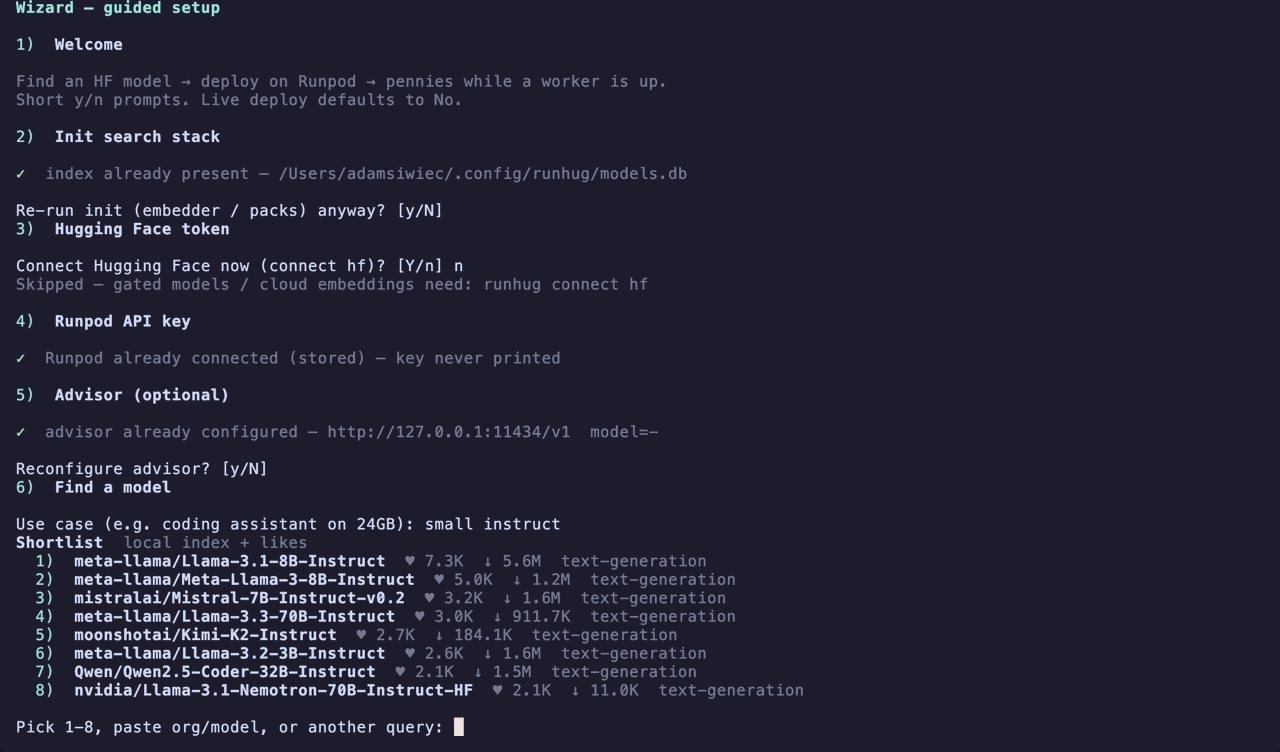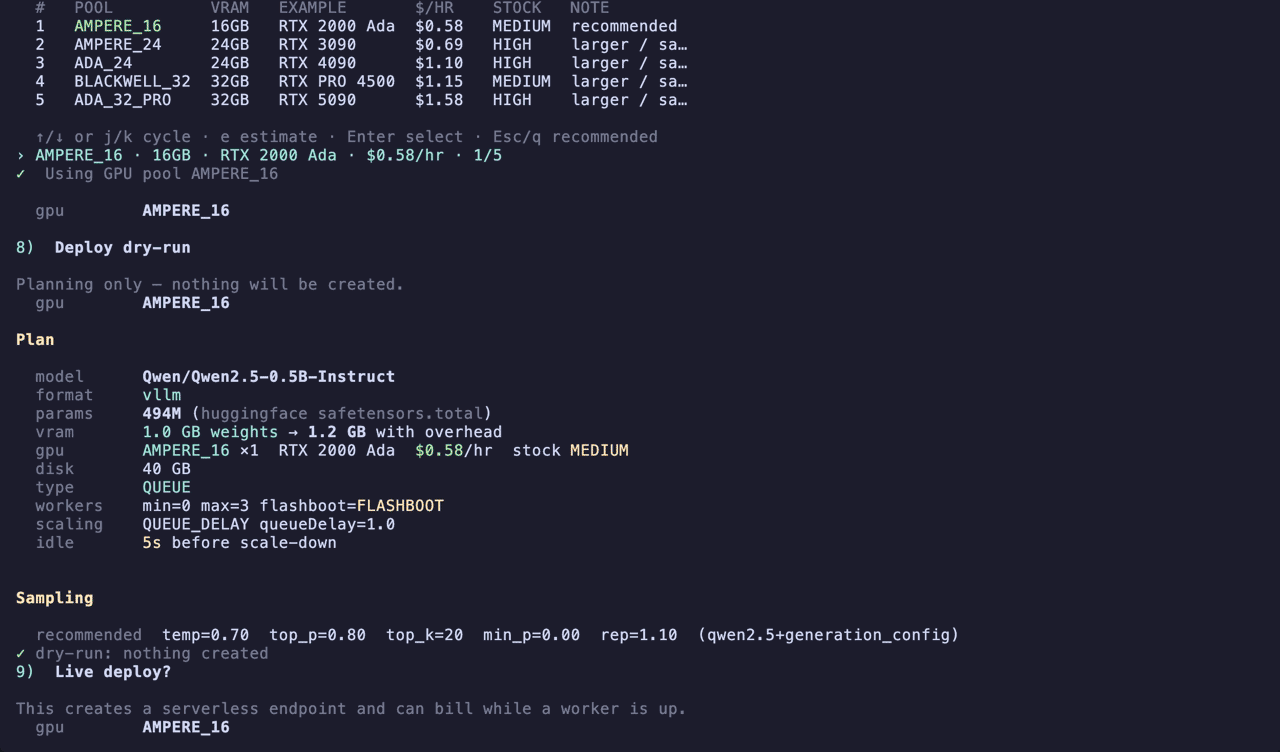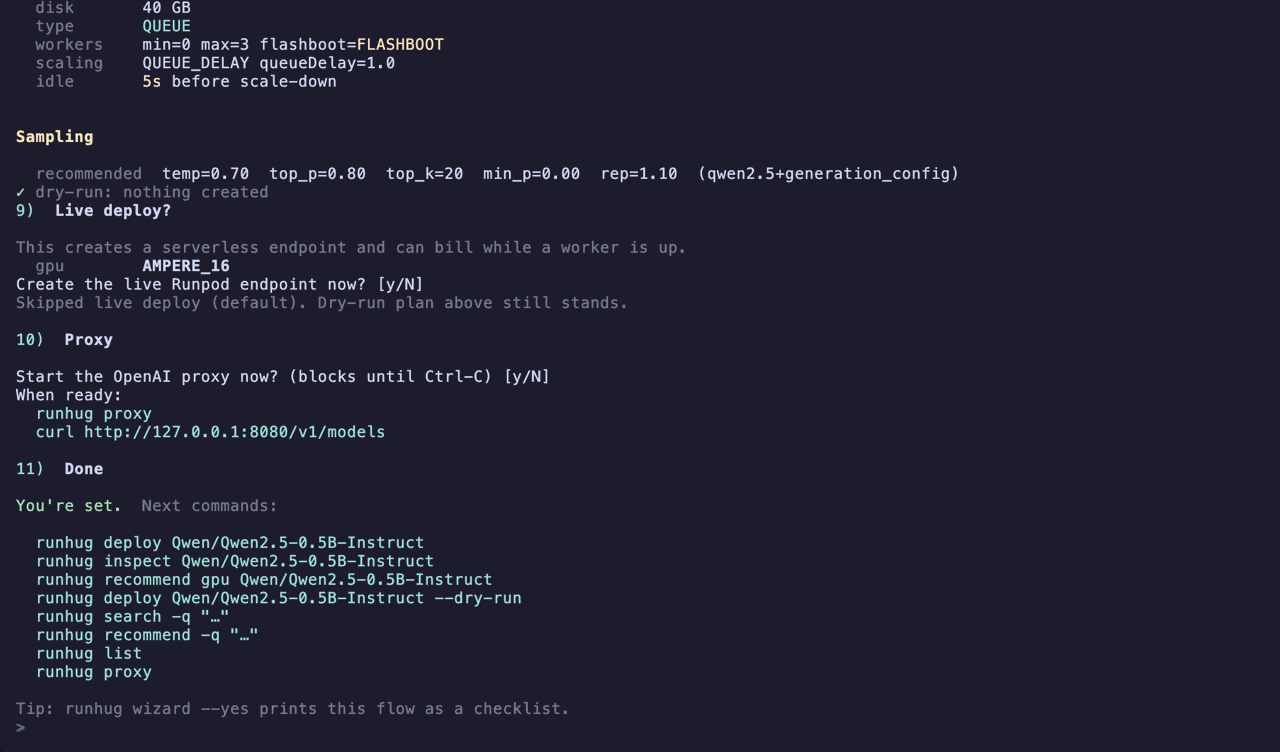
What is runhug?
runhug is an open-source CLI that finds a model, deploys it, and keeps an OpenAI-compatible endpoint in front of Claude Code, OpenCode, or a local chat REPL.
- [*]
Hugging Face search Query the Hub and local index packs, then inspect a row before you spend GPU time.
- [*]
GPU pick and dry-run Recommended / none / customize sampling, with --estimate for cold, warm, and daily cost.
- [*]
RunPod or GCP Serverless vLLM on RunPod, or Spot llama.cpp on GCP — GGUF repos default to GCP.
- [*]
OpenAI-compatible URL Chat through runhug run or runhug proxy at 127.0.0.1. Same /v1 surface for other clients.
- [*]
Claude Code and OpenCode runhug start claude and runhug start opencode bridge the deployed model into those agents.
- [*]
Heretic in-CLI Abliterated heretic builds trained from the CLI, then deployed like any other checkpoint.
- [*]
Index packs Category SQLite packs from hfpacks — install and merge locally, no crawl from the CLI.
Get started in 3 commands
Security notes- 1.
Install
- 2.
Connect & index
- 3.
Wizard
Run · agents · heretic · packs
Terminal tours for chat, agents, abliteration, and local search.
runhug run
Fullscreen chat REPL — streaming, sessions, slash commands.
- [*]Starts fullscreen against any …/v1 (RunPod, GCP, Ollama).
- [*]/mini restores scrollback; /exit or Ctrl-D to quit.
Live from GitHub
openhat-security/runhug · MIT · v0.4.4 · 30m ago · 132 commits
FAQ
What is runhug?
An open-source CLI to search Hugging Face, deploy a checkpoint on RunPod serverless vLLM or GCP Spot llama.cpp, then chat through an OpenAI-compatible URL, Claude Code, or OpenCode — including heretic builds trained in-CLI.
How do I use runhug?
Install from the tabs above, then run runhug wizard. Search a model, dry-run a deploy, then deploy. Chat with runhug run or bridge with runhug start claude / runhug start opencode.
Do I need extra AI subscriptions?
No. The CLI is free (MIT). You pay the GPU provider you choose (RunPod or GCP) and optionally a Hugging Face token for gated models. You can also run locally.
Can I use my existing cloud accounts?
Yes. RunPod uses RUNPOD_API_KEY. GCP uses your gcloud project, IAP/SSH tunnel, and a per-instance Bearer. Keys stay in ~/.config/runhug.
Is it only a terminal app?
The product is a CLI, plus an OpenAI-compatible proxy so Claude Code, OpenCode, and other clients can talk to the same endpoint.
How much does runhug cost?
The agent/CLI is free. Compute is metered by RunPod or GCP Spot. Use --estimate / -e for cold/warm/daily scenarios before you deploy.
What about data and privacy?
Your code is not uploaded to a runhug service. Inference runs on your RunPod workers or GCP VM. Default GCP create uses no public IP; the model port binds loopback behind a tunnel.
Is runhug open source?
Yes. MIT. Issues and PRs are welcome on GitHub.
Collaborate
Looking to collaborate — or searching for offensive security / AI red-team work?
Check out OpenHat Security on GitHub — RunHug, hfpacks, and related tooling live there. If you want to contribute packs, heretic pipelines, deploy backends, or talk about engagements that need model-side security research, email Adam.